Same pictures, 2023 to now
46 AI models, old and new, each drew the same 5 things from one short message, using nothing but circles, boxes and lines. A judge AI could tell what 204 of the 229 first tries were.
GPT-6 Luna saw each picture and picked one of 12 words. I did the same for 30 of them without knowing the model or its answer, and we agreed on 26 of 30. Scores below are "named N of 5": how many of a model's first tries the judge got right.
Five models drew everything three times. Their scores barely moved between tries (GPT-3.5 Turbo 3, 3, 3; GPT-6.1 Sol 5, 5, 5; Claude Sonnet 4 5, 5, 5; Claude Sonnet 5.5 4, 5, 5; DeepSeek V4 Flash 5, 4, 5). GPT-3.5 Turbo to GPT-6.1 Sol is 9 to 15 of 15; Claude Sonnet 4 to Claude Sonnet 5.5 is 15 to 14 of 15. By the rule I set before running (a gap of 7 or more of 15), that is "about the same" in both cases: almost every model from 2023 on draws a cat you can tell is a cat. The judge does not say which cat looks better.
6 models that think more when asked drew everything three more times on the "high" setting (DeepSeek V4 Flash 15 of 15, Gemini 2.5 Flash 15 of 15, Gemini 3.8 Flash 15 of 15, Qwen3.7 Max 15 of 15, Grok 4.7 15 of 15, GPT-6.1 Sol 15 of 15). 0 of 6 rose by 3 or more, so thinking harder did not change how often the drawings were recognised. After that, every model with a thinking setting (27 of 46) drew the five things once more on high: the judge named 132 of 135. 3 of them did not think at all even on high. Each row says how much thinking was measured; tap a picture to see the thinking-hard tries beside the quick ones.
Four models drew a cat and a house twice with the limit raised to 100. Shapes used: Claude Opus 5.5 cat 26 and 32, house 19 and 17; GPT-6.1 Sol cat 41 and 36, house 19 and 21; Claude Haiku 4.5 cat 17 and 17, house 8 and 8; Kimi K3 cat 23 and 15, house 14 and 13. The judge named 14 of 16, against 7 of 8 at 40. The limit stays at 40.
Named is a low bar. Nearly every model clears it, so a score of 5 does not mean a model draws well, and no score here ranks one maker against another.
Tap any picture to see it bigger, with the other tries where there are any. A red ? means the judge could not tell what it was.
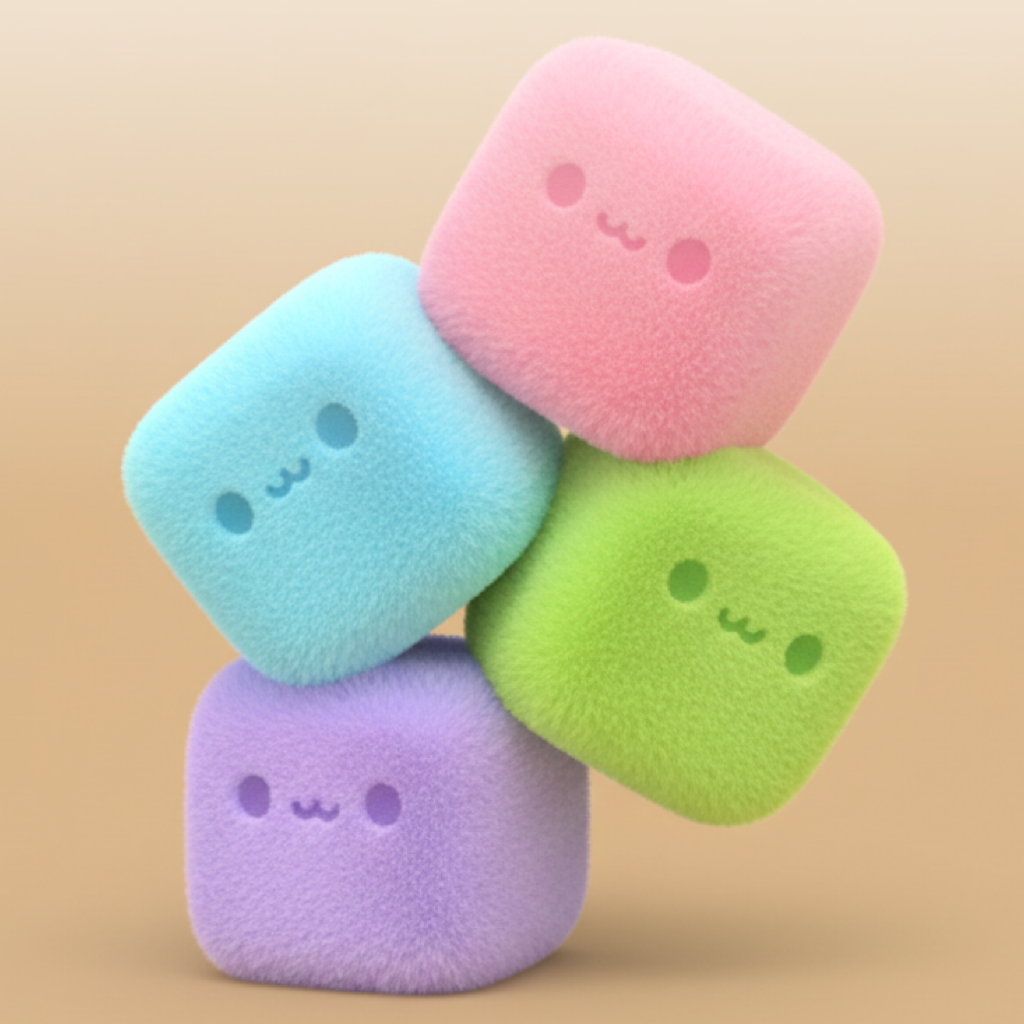
These are real snug blocks, from my game SnugBlox. The models never saw them. They were only told to draw: "a soft pink square with rounded corners, two black dot eyes and a small smile".
How it was done
- Each picture is one message to the model and one reply. No other instructions, no tools, and no memory between pictures.
- The model does not make an image. It writes a list of up to 40 shapes with positions and colours, and this page draws them. Nothing the model wrote is run as code. A shape the page could not read is left out and the row says so.
- The plan, the models, the rules for each result and the spending caps were written down and saved before the first paid call (research/tests/same-picture/prereg-v2.md in the site's code). Version 1's pictures are the first tries here; nothing was redrawn.
- Thinking was asked to be as low as each model allows for the main pictures, and as high as it allows for the thinking-hard set. The note beside each name says what was measured, not what was asked for: 12 models thought anyway when asked not to, and 3 did not think when asked to. Models with no thinking setting at all (the older ones) have no thinking-hard set.
- The "thinking hard" set: 12 models were asked for one cat on their highest thinking setting; the 6 cheapest whose thinking at least doubled then drew all 5 things three times that way. Claude Opus 5.5 was not tried: one such call could have cost more than the probe's cap had left.
- The judge, GPT-6 Luna, was shown each picture at 384 pixels with the question "What is it meant to be?" and these 12 words in a shuffled order: cat, tree, house, smiling block, axolotl, dog, flower, tent, robot, pig, octopus, fish. Only an exact word counts. It is an OpenAI model, so OpenAI rows carry a note.
- A reply cut off before it finished was asked for once more with twice the room, and both are kept. Rate limits were retried after 30, 60 and 120 seconds. One picture is still missing because Mistral kept refusing the call.
- Models are reached through OpenRouter, each pinned to one host: the maker's own where it still serves the model. These ran elsewhere: Claude Sonnet 4 (Amazon Bedrock), Claude Opus 4.1 (Amazon Bedrock), Kimi K2 (Novita), Kimi K2.5 (Amazon Bedrock), Qwen 2.5 72B (DeepInfra), Qwen3 235B (DeepInfra), DeepSeek V3 (DeepInfra), DeepSeek V3.1 (CoreWeave), DeepSeek V3.2 (AtlasCloud), DeepSeek V4 Flash (AtlasCloud), Llama 3.1 70B (Amazon Bedrock), Llama 3.3 70B (AkashML), Llama 4 Maverick (DigitalOcean).
- Cost: version 1 $4.34; version 2 $5.03 (judging $0.02, repeat tries $0.27, thinking hard $4.58, 100 shapes $0.17).
- The models: GPT-3.5 Turbo (openai/gpt-3.5-turbo, on OpenRouter since 2023-05-27); GPT-4 (openai/gpt-4, on OpenRouter since 2023-05-27); GPT-4o (openai/gpt-4o, on OpenRouter since 2024-05-12); GPT-5 (openai/gpt-5, on OpenRouter since 2025-08-07); GPT-5.5 (openai/gpt-5.5, on OpenRouter since 2026-04-24); GPT-6.1 Sol (openai/gpt-6.1-sol, on OpenRouter since 2026-09-29); Claude Sonnet 4 (anthropic/claude-sonnet-4, on OpenRouter since 2025-05-22); Claude Sonnet 4.5 (anthropic/claude-sonnet-4.5, on OpenRouter since 2025-09-29); Claude Sonnet 4.6 (anthropic/claude-sonnet-4.6, on OpenRouter since 2026-02-17); Claude Sonnet 5 (anthropic/claude-sonnet-5, on OpenRouter since 2026-06-30); Claude Sonnet 5.5 (anthropic/claude-sonnet-5.5, on OpenRouter since 2026-09-28); Gemini 2.5 Flash (google/gemini-2.5-flash, on OpenRouter since 2025-06-17); Gemini 3 Flash (google/gemini-3-flash-preview, on OpenRouter since 2025-12-17); Gemini 3.5 Flash (google/gemini-3.5-flash, on OpenRouter since 2026-05-19); Gemini 3.8 Flash (google/gemini-3.8-flash, on OpenRouter since 2026-09-02); Claude Opus 4.1 (anthropic/claude-opus-4.1, on OpenRouter since 2025-08-05); Claude Haiku 4.5 (anthropic/claude-haiku-4.5, on OpenRouter since 2025-10-15); Claude Opus 4.5 (anthropic/claude-opus-4.5, on OpenRouter since 2025-11-24); Claude Opus 5 (anthropic/claude-opus-5, on OpenRouter since 2026-07-24); Claude Fable 5.1 (anthropic/claude-fable-5.1, on OpenRouter since 2026-09-01); Claude Opus 5.5 (anthropic/claude-opus-5.5, on OpenRouter since 2026-09-22); Claude Haiku 5.5 (anthropic/claude-haiku-5.5, on OpenRouter since 2026-10-07); Kimi K2 (moonshotai/kimi-k2, on OpenRouter since 2025-07-11); Kimi K2.5 (moonshotai/kimi-k2.5, on OpenRouter since 2026-01-26); Kimi K2.6 (moonshotai/kimi-k2.6, on OpenRouter since 2026-04-20); Kimi K3 (moonshotai/kimi-k3, on OpenRouter since 2026-07-16); Qwen 2.5 72B (qwen/qwen-2.5-72b-instruct, on OpenRouter since 2024-09-18); Qwen3 235B (qwen/qwen3-235b-a22b-2507, on OpenRouter since 2025-07-21); Qwen3.5 Plus (qwen/qwen3.5-plus-02-15, on OpenRouter since 2026-02-16); Qwen3.7 Max (qwen/qwen3.7-max, on OpenRouter since 2026-05-21); Qwen3.8 Max Prime (qwen/qwen3.8-max-prime, on OpenRouter since 2026-09-23); DeepSeek V3 (deepseek/deepseek-chat, on OpenRouter since 2024-12-26); DeepSeek V3.1 (deepseek/deepseek-chat-v3.1, on OpenRouter since 2025-08-21); DeepSeek V3.2 (deepseek/deepseek-v3.2, on OpenRouter since 2025-12-01); DeepSeek V4 Flash (deepseek/deepseek-v4-flash, on OpenRouter since 2026-04-23); DeepSeek V4.1 Flash (deepseek/deepseek-v4.1-flash, on OpenRouter since 2026-09-10); Grok 4.20 (x-ai/grok-4.20, on OpenRouter since 2026-03-31); Grok 4.5 (x-ai/grok-4.5, on OpenRouter since 2026-07-08); Grok 4.7 (x-ai/grok-4.7, on OpenRouter since 2026-09-21); Mistral Large (mistralai/mistral-large, on OpenRouter since 2024-02-25); Mistral Large 2 (mistralai/mistral-large-2407, on OpenRouter since 2024-11-18); Mistral Large 3 (mistralai/mistral-large-2512, on OpenRouter since 2025-12-01); Mistral Large 4 (mistralai/mistral-large-4-0, on OpenRouter since 2026-10-06); Llama 3.1 70B (meta-llama/llama-3.1-70b-instruct, on OpenRouter since 2024-07-22); Llama 3.3 70B (meta-llama/llama-3.3-70b-instruct, on OpenRouter since 2024-12-06); Llama 4 Maverick (meta-llama/llama-4-maverick, on OpenRouter since 2025-04-05).
The message a model gets
Draw {thing} using simple shapes.

The canvas is 100 wide and 100 tall. The point 0,0 is the top left corner. Reply with a JSON list of shapes. Shapes are drawn in order, so later shapes sit on top of earlier ones. Each shape is one of these five kinds:
{"shape":"circle","x":50,"y":50,"r":10,"color":"#3366cc"}
{"shape":"ellipse","x":50,"y":50,"rx":20,"ry":10,"color":"#cc9933"}
{"shape":"rect","x":10,"y":10,"w":30,"h":20,"color":"#339966"}
{"shape":"polygon","points":[[10,10],[50,90],[90,10]],"color":"#993399"}
{"shape":"line","x1":10,"y1":10,"x2":90,"y2":90,"width":2,"color":"#333333"}

Use at most 40 shapes. Reply with the JSON list and nothing else.
Where it says {thing}: "a cat"; "a tree"; "a house"; "a snug block: a soft pink square with rounded corners, two black dot eyes and a small smile"; "a cute pink axolotl plush toy with big eyes and lighter pink gills". For the 100 shape check, "40" became "100" and nothing else changed.
What this cannot tell you
- Which AI is best. It says who drew a recognisable cat, tree, house, block and axolotl for this message, and little more.
- Whether the judge is right. It is a model, checked against one person's 30 taps.
- Four years of progress in a straight line. Hosts, shrunk copies and listing dates differ, and the year is when the model was first listed on OpenRouter.
- How a model draws things it has never seen drawn. These five are picked by taste, and cartoon cats are everywhere.
- What another wording would do. One message was tested. Snapshots behind a model name can also change, so a rerun next month may differ.